LLM Models
Choose your LLM based on use case
Regal offers multiple leading Large Language Models (LLMs) to power your AI agents for phone and SMS conversations. Each is optimized for different use cases, so the best choice depends on your goals, call type, complexity of conversation, and cost tolerance.
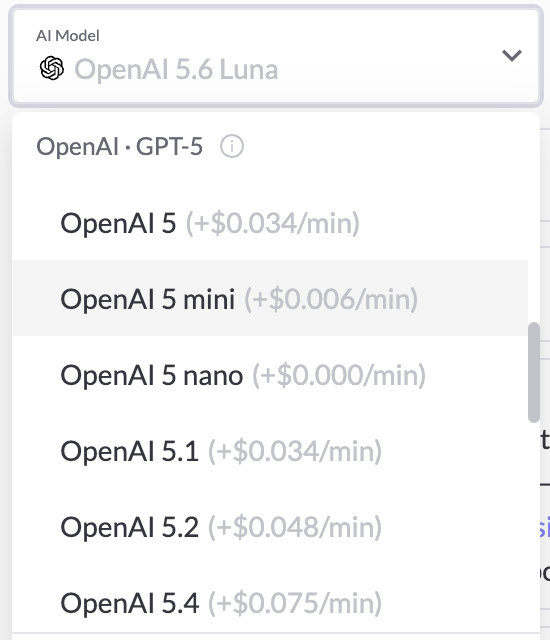
We recommend starting with OpenAI GPT-5.6 Luna, Regal's default model and top pick for most production agents. Upgrade to a higher-performing model only if your agent isn't handling the call as well as you'd like and you're willing to pay more for it.
📘 How we rate modelsThe guidance on this page comes from Regal’s internal model evaluations, which run every model through the same set of real and synthetic voice conversations (scheduling, qualification, support, negotiation, authentication, transfers) and assess:
- Task completion: how reliably the agent moves the call forward to its goal
- Action (tool) calling: whether the agent calls actions when it should, and holds off when it shouldn't
- Speed: time until the agent starts responding
- Cost: relative cost per conversation turn
Quick comparison
| Model | Tier | Task completion | Speed | Relative cost |
|---|---|---|---|---|
| GPT-4.1 | Standard | High (top) | Fast | $$$ |
| GPT-5.6 Terra | Standard | Good | Moderate | $$$ |
| GPT-5.6 Luna ⭐ (default) | Lightweight | Good | Moderate | $ (lowest) |
| GPT-4.1 Mini | Lightweight | Good | Fast | $$ |
| Gemini 3.6 Flash | Standard | Good | Moderate | $$ |
| GPT-4o Mini | Lightweight | Moderate | Fast | $ |
| Gemini 3.5 Flash-Lite | Lightweight | Moderate | Fast | $$ |
| GLM-4.7 (beta) | Standard | Moderate | Fastest | $$ |
| GPT-5.4 Mini | Lightweight | Lower | Fast | $$ |
| Claude Haiku 4.5 | Lightweight | Lower | Fastest | $ |
| GPT-4o | Standard | High | Slower | $$$$ |
| Claude Sonnet 4.6 | Standard | High | Slowest | $$ |
Rules of thumb
- Best overall value: GPT-5.6 Luna. Strong all-around performance at the lowest cost of any model we offer.
- Most capable for complex calls when cost matters less: GPT-4.1 or GPT-5.6 Terra.
- Fastest responses: GLM-4.7, Claude Haiku 4.5, Gemini 3.5 Flash-Lite, GPT-4o Mini.
- Most reliable action calling: Gemini 3.6 Flash, GPT-4o, GPT-5.6 Luna.
- Long, multi-step calls where finishing the task matters most: GPT-4.1, then GPT-4o or Claude Sonnet 4.6 (both slower to respond).
Voice CX Benchmark Scores
Scores below are from Regal's public Voice CX Benchmark, filtered to the models available in Regal. The Voice CX Score (out of 1,000) combines task progression, accuracy and safety, clarity and coherence, personalization, and speed, and is weighted most heavily on task progression and latency. See the benchmark page for the full leaderboard and methodology.
| Rank | Model | Voice CX Score | Task progression | Accuracy & safety | Clarity & coherence | Personalization & engagement | Time to first token (p50) | Cost per 1K turns |
|---|---|---|---|---|---|---|---|---|
| 1 | GPT-4.1 | 785 | 62.6 | 77.1 | 84.3 | 85.0 | 793 ms | $25.34 |
| 2 | GPT-5.6 Luna | 766 | 57.2 | 77.0 | 84.3 | 85.2 | 988 ms | $1.18 |
| 3 | GPT-4.1 Mini | 764 | 58.0 | 77.3 | 82.5 | 82.7 | 810 ms | $5.18 |
| 4 | GPT-5.6 Terra | 756 | 58.8 | 74.6 | 85.0 | 83.7 | 1,042 ms | $11.26 |
| 5 | Gemini 3.6 Flash | 750 | 56.0 | 77.6 | 83.0 | 84.1 | 1,031 ms | $8.65 |
| 6 | Gemini 3.5 Flash-Lite | 741 | 53.1 | 74.7 | 82.0 | 82.4 | 755 ms | $3.75 |
| 7 | GPT-4o Mini | 740 | 53.6 | 74.0 | 81.3 | 82.2 | 766 ms | $2.41 |
| 8 | GPT-5.4 Mini | 739 | 51.3 | 75.0 | 83.9 | 83.5 | 842 ms | $4.56 |
| 9 | GLM-4.7 (beta) | 732 | 52.7 | 72.8 | 81.0 | 80.8 | 584 ms | $4.44 |
| 10 | Claude Haiku 4.5 | 711 | 48.1 | 67.9 | 80.8 | 85.2 | 662 ms | $1.83 |
| 11 | GPT-4o | 674 | 60.1 | 77.8 | 83.6 | 82.9 | 1,305 ms | $39.69 |
| 12 | Claude Sonnet 4.6 | 623 | 59.9 | 75.9 | 84.5 | 84.5 | 2,197 ms | $3.52 |
Models available in Regal that aren't yet in the benchmark: GPT-4.1 Nano, GPT-5, GPT-5 Mini, GPT-5 Nano, GPT-5.1, GPT-5.2, GPT-5.4, GPT-5.4 Nano, Claude Sonnet 4.5, Gemini 3.5 Flash, Gemini 3.1 Flash-Lite, and the GPT Realtime models.
OpenAI GPT-5.6 Series
GPT-5.6 Luna (Regal default & top pick)
GPT-5.6 Luna (Regal default & top pick)
Best for most production voice agents, especially high-volume or cost-sensitive ones
Examples: Qualification, scheduling, confirmations, information capture, routing, straightforward support
✅ Pros: Lowest cost per turn of any model Regal offers, and included in Regal base AI voice agent minute pricing. Strongest in its generation at calling actions when required. Sequences confirmations correctly before taking an action.
❌ Cons: May read an unfilled contact field or variable aloud as raw text (e.g., {{offer_amount}}) instead of treating it as missing, so make sure every variable referenced in the prompt is populated or has a fallback. Slightly behind Terra on completing long, multi-step tasks.
GPT-5.6 Terra
Best for multi-step conversations, conditional workflows and more nuanced customer requests
Examples: Screening calls with policy boundaries, multi-step support, calls with several actions
✅ Pros: Delivers policy-boundary and compliance lines cleanly.
❌ Cons: About 10x Luna’s cost. Weakest in its generation at calling required actions. Can call a lookup action before acknowledging the caller, and can repeat the same question while a different required field goes unasked. Spell out the order of steps and acknowledgments explicitly.
OpenAI GPT-4.1 Series
GPT-4.1
GPT-4.1
Best for longer, more complex calls where conversation quality and task completion matter most
Examples: Long qualification calls with 10+ steps or conditional branches, open-ended support, calls with multiple or iterative custom actions, complex reasoning (e.g., dynamic quote estimates)
✅ Pros: Highest task completion of all in-app models. Fast. Reliably refuses to claim an action succeeded when it returned bad data.
❌ Cons: Higher cost. GPT-4.1 Mini is a strong alternative at roughly a fifth of the cost. In some negotiation-style calls it opened by restating its own instructions instead of greeting the caller; a clear static or scripted greeting avoids this.
GPT-4.1 Mini
Best for short-to-medium conversations where strict instruction following is needed (improvisation not valued)
Examples: Confirmation, scheduling, collections, qualification calls with < 25 questions
✅ Pros: Reliable instruction following at much lower cost than GPT-4.1. Fast. Enforces authentication steps rather than skipping them.
❌ Cons: Was observed telling a caller an action succeeded ("you'll receive a confirmation email shortly") after the action actually failed. Instruct the agent to confirm outcomes only after a successful action response.
GPT-4.1 Nano
Best for very simple, high-volume tasks
Smallest and lowest-cost GPT-4.1 model. Suited to narrow, well-defined tasks; test carefully before using it on multi-step calls.
OpenAI GPT-4o Series
GPT-4o Mini
GPT-4o Mini
Best for short, simple, cost-sensitive use cases (e.g., calls normally staffed out of low-cost locales)
Examples: Confirmation, scheduling, collections, qualification calls with < 15 questions and little branching
✅ Pros: Fast and low cost. Holds a firm line in negotiations without inventing outcomes.
❌ Cons: Weaker at reasoning (use a custom action for math). On calls that collect many fields, it can ask for nearby details instead of the one required field still missing, so list required fields explicitly. GPT-5.6 Luna costs less and completes tasks more reliably.
GPT-4o
Best for calls that depend heavily on actions being called correctly
✅ Pros: Among the most reliable models at calling required actions and at completing tasks. Reliably declines to claim success after a failed action.
❌ Cons: Among the most expensive and slower to respond. Closing and verification turns are often technically correct but stop short of what was asked. For most use cases GPT-4.1 is a better choice.
OpenAI GPT-5 Series
- GPT-5.4: Advanced model for complex professional workflows, with strong reasoning, instruction following, action calling and long-context performance.
- GPT-5.4 Mini: Faster, lower-cost version of GPT-5.4. ✅ Keeps context cleanly across an internal agent handoff without re-greeting the caller. ❌ Can call downstream actions (e.g., sending data to a CRM) before all required fields are collected. Completes tasks less reliably than GPT-4.1 Mini and GPT-4o Mini, so those are usually better lightweight picks.
- GPT-5.4 Nano: Lightweight GPT-5.4 model optimized for speed and cost on simple, high-volume tasks such as classification, data extraction, routing and structured information capture.
- GPT-5.2: Conversational model for complex workflows, with stronger reasoning and instruction adherence on long, multi-step conversations.
- GPT-5.1: General-purpose conversational model with stable reasoning and consistent performance across multi-turn conversations.
- GPT-5: Full model for high-stakes or complex conversations requiring domain knowledge, multi-step reasoning and long-context recall.
- GPT-5 Mini: Balanced option for mixed workloads needing stronger reasoning at moderate cost.
- GPT-5 Nano: Ultra-lightweight option for high-volume, low-cost interactions (e.g., confirmations, reminders).
For most new agents, GPT-5.6 Luna or Terra outperform the earlier GPT-5 models.
When to Consider Claude
Anthropic's Claude models are strong at nuanced language and keeping context, but in voice the Sonnet models are slower to respond than comparable OpenAI and Gemini options, and Claude models are more likely to take an action without first confirming it with the caller. If you use Claude, explicitly instruct the agent to confirm with the caller before any action that changes data (booking, assigning, updating).
- Claude Haiku 4.5: Very fast to respond. Holds a negotiated price ceiling without revealing its limit. Lower task completion than other lightweight models.
- Claude Sonnet 4.6: The strongest Claude model for voice: high task completion and good at holding off on actions when they aren't needed. Slow to respond. Can read unfilled variables aloud, or tell the caller it is using placeholder values when contact data is missing.
- Claude Sonnet 4.5: Balanced Claude model for longer, more complex reasoning tasks.
When to Consider Gemini
Google's Gemini models offer low latency and low cost.
- Gemini 3.6 Flash: The most reliable in-app model at calling required actions at moderate cost. Tends to answer policy/FAQ questions from its own knowledge instead of using your knowledge base, so tell it explicitly to check the knowledge base before answering those questions.
- Gemini 3.5 Flash-Lite: Low cost and fast. Occasionally returns an empty response when an action errors, and can pass the wrong value to an action (e.g., the wrong department), so use clear, enumerated options for action inputs.
- Gemini 3.5 Flash: Balanced Gemini model for general conversational workloads.
- Gemini 3.1 Flash-Lite (preview): Lightweight, low-cost model for high-volume, narrowly scoped conversations.
Open Weight Model (in Beta)
Regal can provide an open source model option on request, on a case by case basis. We use GLM-4.7, an open-weight large language model developed by Zhipu AI (zai-org), available at https://huggingface.co/zai-org/GLM-4.7
✅ Pros: The fastest-responding in-app model, at low cost. Refuses to claim success when an action returns incomplete data.
❌ Cons: Can ask a confirmation question and take the action in the same turn instead of waiting for the caller's answer, so instruct it to wait for a "yes" before acting. Completes tasks less reliably than GPT-4.1 and GPT-5.6 models.
Realtime (Speech-to-Speech) Models
Regal also supports OpenAI's realtime speech-to-speech models (GPT Realtime, GPT Realtime 1.5, GPT Realtime 2 and GPT Realtime Mini), which process audio directly rather than converting speech to text first. Contact us to discuss whether a realtime model fits your use case.
Common Issues by Model, and How to Prompt Around Them
The fixes below build on techniques in Prompting Best Practices.
| If you see... | Most often seen with | Try |
|---|---|---|
The agent reads {{variable}} text aloud | GPT-5.6 Luna, Claude Sonnet 4.6 | Add an early step that checks whether the value is blank or contains # or 0, with a fallback line (see Empty Values for Dynamic Variables in Prompting Best Practices) |
| The agent takes an action without confirming with the caller | Claude models, GLM-4.7 | Ask the confirmation question as its own turn, then branch with If yes, CALL <action> AND SAY "..." (see Reliable Action Invocation) |
| The agent fires the wrong end-call action, or hangs up from the wrong branch | Any model | Use named end-call actions (e.g., end_call_voicemail, end_call_unavailable) instead of one generic End Call |
| The agent says something succeeded when the action failed | GPT-4.1 Mini | Instruct the agent to only confirm outcomes after a successful action response |
| The agent answers FAQs from general knowledge instead of your KB | Gemini 3.6 Flash | Tell the agent to check the knowledge base before answering policy or product questions |
| The agent asks the wrong question while a required field is still empty | GPT-4o Mini, GPT-5.6 Terra | List the required fields explicitly and the order to collect them |
| The agent calls an action before collecting everything it needs | GPT-5.4 Mini | State which fields must be collected before the action is called |
Switching Between Models
Always retest when you change models; a prompt tuned for one model won't transfer cleanly to another. Run simulations before full rollout.
- Moving from GPT-4.x to GPT-5.x (e.g., GPT-4o Mini → GPT-5.6 Luna): GPT-5.x models need much less defensive scaffolding. Prompts written for GPT-4o Mini or GPT-4.1 Mini can usually be cut by about half, including the longer voicemail and iOS screener handling those models need.
- Moving to a lightweight model: Lightweight models follow explicit structure best. Use numbered steps,
If ...branches and exactsay:lines. - Moving to Claude or GLM-4.7: Add explicit confirmation steps before any action that changes data (see Common Issues above).
If you're stuck after a few prompt attempts, ask Regal Copilot for suggestions, and tell it which model the agent uses.
Still not sure? Reach out – we're happy to help tune your agent for best performance.
Want Regal to offer a different LLM? Just reach out – we're constantly evaluating new models and onboarding those with differentiated performance.
Want to bring your own LLM? Contact us – we'll help you integrate it into Regal.
Updated 4 days ago